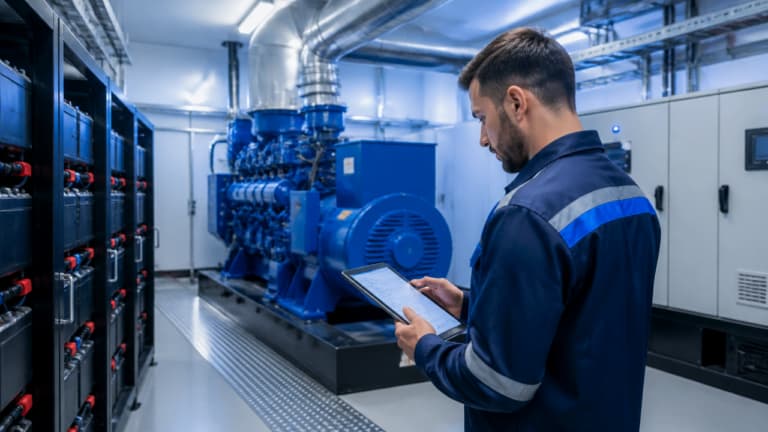
A good energy backup audit does not start with the report, it starts with the right question: if power fails right now, what really keeps running and for how long? This roadmap is useful for infrastructure managers, clinical engineering, facilities, IT and quality teams who need to validate generators, UPS systems and battery banks in critical environments. The goal here is to transform the audit into a practical routine, focused on operational risk, evidence and corrective action.
Beyond compliance, the review must show whether the system responds in the expected timeframe, sustains essential loads and maintains traceability. This is where solutions like the DROME platform help, because they connect continuous monitoring, operational history and analytical intelligence to anticipate deviations before failure.
Key questions the audit must answer
- Which loads are truly critical and what autonomy each one requires.
- Whether generator, UPS and batteries operate as an integrated system, not as isolated assets.
- Whether there is recent evidence of transfer testing, startup, autonomy and return to normal condition.
- Which degradation signals have already appeared and have not yet become an action plan.
- Who approves, executes, records and revalidates each correction found.
What must be included in the audit scope
The scope must cover the entire electrical continuity chain. Auditing only the generator or only the UPS creates a false sense of security, because failure usually appears precisely at the interface between equipment, switching logic and operational procedure.
In practice, the review should consider power sources, panels, transfer switches, UPS, battery banks, generator exhaust and fuel system, grounding, alarms, sensors and maintenance records. It is also worth confirming which loads are connected to the contingency circuit and whether there have been changes in layout, bed expansion, new freezers, incubators or servers since the last validation.
What is an energy backup system?
It is the set of assets and routines that keep operations running when the utility fails. In critical environments, this includes uninterrupted power for sensitive loads, automatic generator startup and sufficient sustaining time for the process to continue safely.
This definition seems simple, but guides an important decision: the audit must assess actual readiness for use. If the installation depends on manual intervention, if the calculated autonomy does not match current load or if alarms do not reach the right team, the system exists on paper but does not protect operations as it should.
Practical checklist for technical inspection
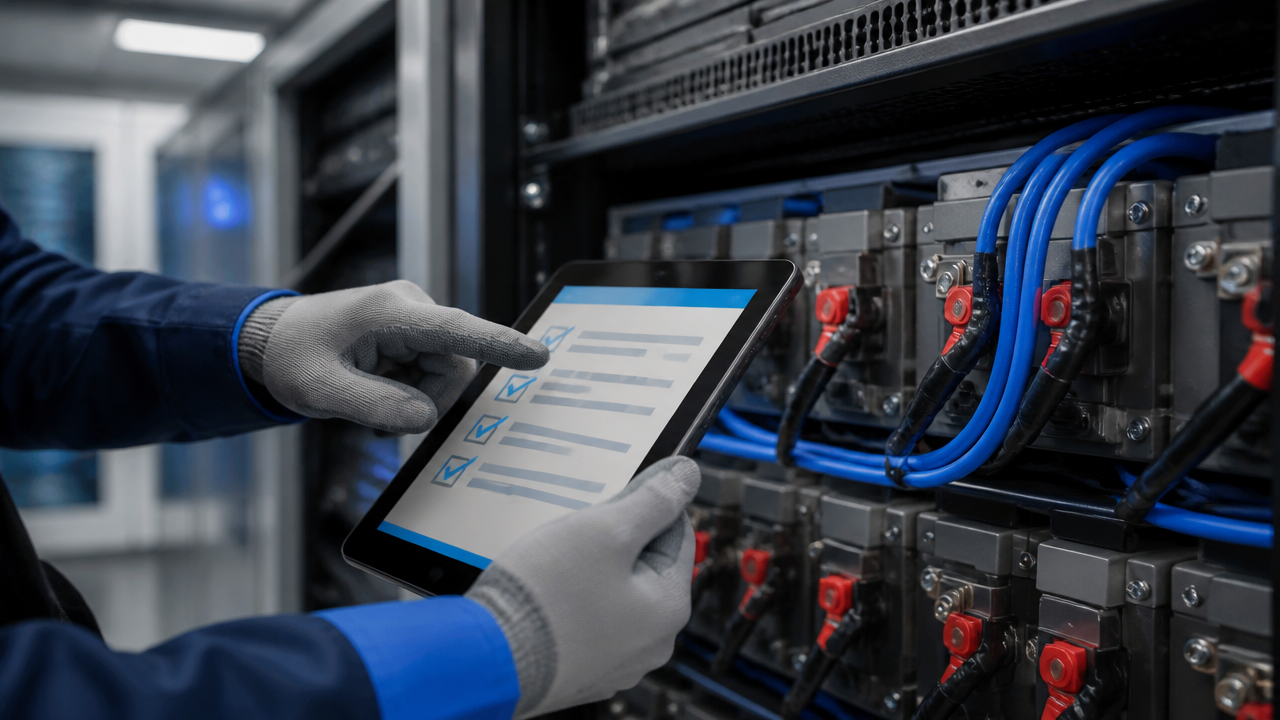
The checklist works best when each item answers an objective criterion: compliant, non-compliant or requires additional validation. This avoids vague reports and facilitates risk prioritization.
| Audited block | What to check | Expected evidence |
|---|---|---|
| Generator | Automatic startup, fuel level, leaks, exhaust, abnormal noise | Recorded test, visual inspection and parameters within standard |
| UPS | Active alarms, internal temperature, ventilation, applied load, bypass | Event log, status screen and technical report |
| Batteries | Oxidation, swelling, loose connections, voltage, estimated autonomy | Measurements, replacement date and performance history |
| Transfer | Switching time, return to grid, selectivity | Functional test with time and response record |
| Critical loads | Updated list, defined priority, actual power consumption | Validated inventory compatible with installed capacity |
| Documentation | SOP, maintenance, incidents, responsible parties and pending items | Complete traceability and open action plan |
A decisive point is comparing projected capacity with actual load. Technical rooms change, equipment is added and the autonomy promised at commissioning may cease to exist months later. Therefore, the audit must confirm updated numbers, not just repeat the old design document.
Which failures go unnoticed most frequently
The most dangerous problems are the silent ones. Degraded battery, insufficient ventilation, loose terminal, irregular generator startup and out-of-calibration sensors usually evolve without drawing attention until the moment of interruption.
It is also common to find tests performed under unrealistic conditions. The equipment may start, but without representative load, without measuring response time or without validating whether all priority assets remained energized. Serious auditing does not just ask if the system worked, it asks under which conditions, for how long and with what performance.
Another recurring error is separating infrastructure and operations. When engineering, maintenance, IT and clinical staff do not share criteria, the result is an incomplete criticality matrix. The audit must unify these views to define what really cannot stop.
How often should the audit be performed
The ideal frequency follows operational risk, not just the calendar. In high-criticality locations, best practice combines frequent visual inspections, scheduled functional tests and periodic review of documentation, autonomy and load changes.
A simple routine helps maintain consistency:
- visual inspection and alarm checks at short intervals, with defined responsibility;
- periodic functional tests of switching and response;
- monthly or quarterly review of logs, events and pending items;
- more complete audit after load expansion, equipment replacement or critical incident.
The most important thing is not to treat the audit as an isolated event. When it becomes a process, each inspection feeds the next and reduces the chance of operational surprise.
How to implement energy backup safely
Implementing safely means sizing, testing and monitoring. The first step is to map processes that cannot stop, then associate each load with the maximum acceptable downtime and minimum required autonomy.
Next, it is worth validating five points: installed capacity, switching sequence, response time, effective autonomy and human contingency plan. This last item is underestimated. If an alarm sounds at 3 AM, does someone know what to do, in how much time and with what priority? Operational safety depends as much on the asset as on the team's response.
This is where DROME becomes relevant. By consolidating telemetry, alarms and behavior history, the platform helps move away from a purely reactive model. Instead of discovering the problem only at failure, operations can see degradation patterns and act in advance.
How to record evidence and turn findings into action
Audit without evidence becomes opinion. Each verification should leave a clear trail: date, asset, observed condition, photo when applicable, measurement, estimated impact, responsible party and correction deadline.
A practical way to classify findings is to separate by operational criticality:
- high criticality: compromises immediate response, autonomy or essential load safety;
- medium criticality: does not interrupt today, but accelerates degradation or reduces safety margin;
- low criticality: affects organization, documentation or standardization, with no immediate impact.
This method prevents everything from becoming urgent and helps direct budget. The final report should end with decisions, not just observations. If the finding did not generate an owner, deadline and revalidation criterion, the audit is not yet complete.
Why continuous monitoring improves auditing
The best audit is the one that arrives earliest to the problem. Continuous monitoring reduces dependence on point-in-time visits and expands visibility into trends, failure repetition and out-of-pattern behavior.
With AI support, this gain becomes even clearer. Instead of looking only at isolated values of temperature, voltage or transfer time, the system begins to recognize combinations that precede anomalies. For hospitals, laboratories and industrial operations, this means prioritizing maintenance based on actual risk, not just fixed intervals.
In the DROME context, this model connects sensors, history and operational intelligence to support faster decisions. The audit stops being just a snapshot and starts functioning as part of a prevention cycle.
Frequently asked questions
What is an energy backup system?
An energy backup system is the set of generators, UPS systems, batteries, panels and switching routines that keep critical loads operating when the grid fails. In hospitals, laboratories and industries, it must be audited to guarantee actual autonomy, response time and electrical safety.
How often should the audit be performed?
Frequency depends on operational criticality, but the safest practice combines frequent visual inspections, scheduled functional tests and periodic documentation review. Critical environments should not wait for failure to validate the system, because battery autonomy, generator startup and switching can degrade silently.
How to implement energy backup safely?
The starting point is mapping critical loads, validating required autonomy, inspecting UPS systems, batteries, generators, transfer switches and maintenance records. Then, the system must be tested under controlled conditions, results compared with expected standard and action plan opened for each non-conformity found.
What is the difference between audit and system maintenance?
The audit confirms whether the system remains capable of protecting critical operations in the real scenario. Maintenance executes adjustments, replacements and repairs. In other words, the audit measures readiness, traceability and residual risk; maintenance corrects what the audit, tests and monitoring point out.
Is it worth using monitoring and AI in the audit?
Yes, especially when there are many distributed assets, history of failures and requirement for quick response. With continuous monitoring and AI, operations stop depending only on point-in-time inspections and begin identifying early signals, such as abnormal heating, autonomy loss and switching patterns outside expected behavior.
Read next
7 Indicators to Audit Environmental Data Integrity
Learn which indicators reveal failures, gaps, and risks in environmental data integrity for critical operations and how to audit with greate…
Monitoring Software Validation: Key Criteria
Discover the technical criteria for validating monitoring software in IoT, ensuring reliability and regulatory compliance.
SaaS Monitoring Contracts: What to Review
Understand which clauses to review in SaaS monitoring contracts in 2026, with focus on SLA, data, security, integrations, and continuity.