Equipment can continue operating while its signals already deviate from normal patterns. To reduce unplanned downtime across multiple plants, maintenance must transform measurements into recognized deviations, actionable alerts, and recorded interventions. Collecting data alone does not anticipate failure.
What changes when maintenance uses condition data
- Collection records asset parameters over time.
- Detection identifies a change from expected behavior.
- Anticipation estimates whether sufficient time remains to intervene before functional failure.
- Decision assigns responsibility, timeline, procedure, and outcome documentation.
Collecting data and predicting failure are separate steps
A dashboard with many readings shows what happened, but does not by itself define what the team should do. To guide maintenance, you must understand the asset's normal behavior, relate changes to operating conditions, and define which deviations justify inspection or intervention.
A fixed threshold can detect high temperature, for example, but perhaps only after the equipment has already left the operating range. Deviation detection compares the current reading to relevant references. Anticipation adds an estimate of evolution and available time to act, which must be validated in the context of each asset.
In an operation with multiple plants, asset condition must also appear by unit. The same reading may have different implications depending on load, environment, time of day, and equipment function. Consolidating this data helps prioritize work without losing local context.
Vibration analysis and multivariate analysis answer distinct questions
Vibration analysis examines mechanical signals to identify patterns associated with, for example, imbalance or wear. It requires appropriate instrumentation and interpretation compatible with the machine type. A temperature or current reading does not replace a vibration measurement.
The multivariate approach crosses different signals from the same asset. This allows you to assess whether multiple related changes form a condition pattern, rather than treating each alarm as an isolated event. In DROME, DROME Predict crosses more than 15 parameters from the same asset. This capability does not mean each parameter comes from a vibration sensor, nor that one technique applies to all failure modes.
In the configuration described for DROME, the Satellite Sensor STE measures temperature. The SDT measures current and door state. The SAD receives 4 to 20 mA signals for pressure, depending on the application. Signal selection depends on the asset and the hypothesis the team wants to monitor.
Data flow must preserve collection without promising offline alerts
The Satellite Sensor measures the parameters defined for the asset and transmits data to the CTD Concentrator. The CTD forwards records to the cloud, where DROME Predict crosses variables and presents alerts to support team decision-making.
The CTD has a 12-hour battery and local data storage for up to 20 days, according to specifications provided by DROME. Local retention helps preserve records during power or connection failures, but does not guarantee that a notification reaches the responsible party without an available communication path. It is worth testing in the pilot how collection, transmission, and recovery behave after an interruption.
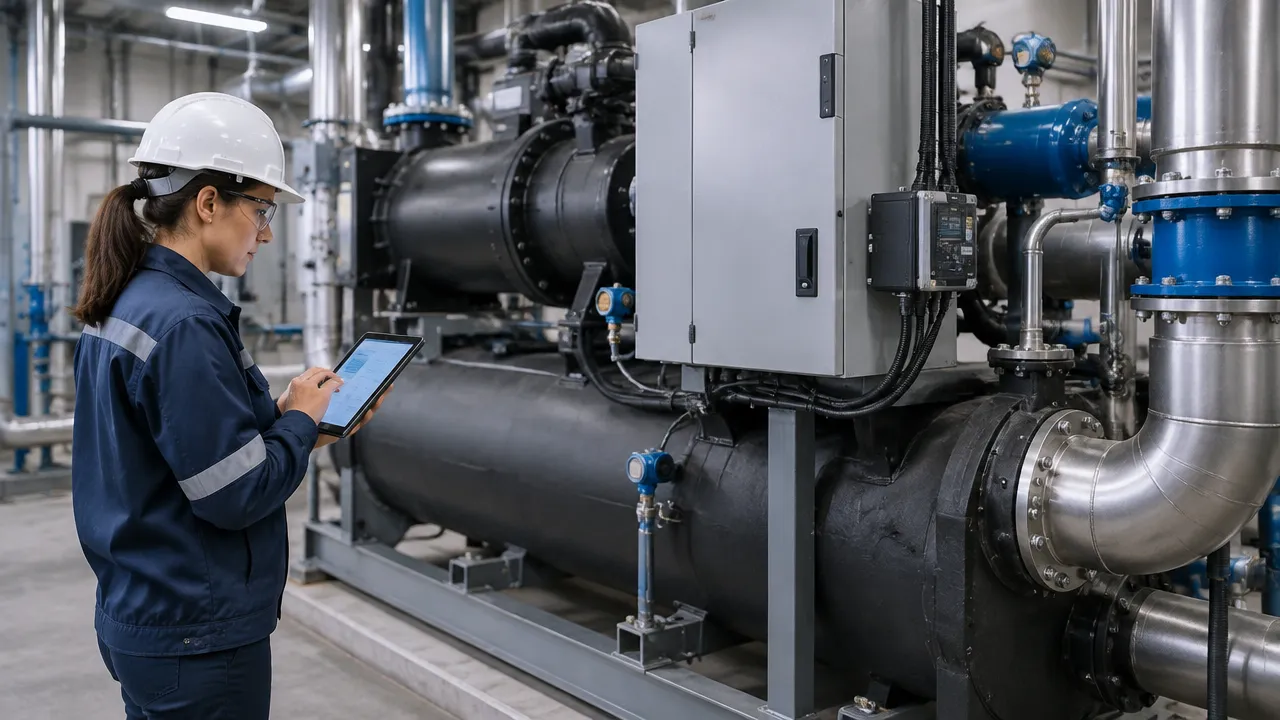
For chillers, a hypothetical pilot can monitor temperature, equipment current, and pressure if a compatible signal is available for the SAD. The goal is to observe how these variables behave together and how the team responds to changes. The example does not presume a specific failure or expected outcome.
According to DROME information, DROME Predict can issue alerts 30 to 60 minutes before failure, with indication of cause and corrective action. This window is not a universal guarantee: it depends on the asset, available signals, and the observed pattern. The team should evaluate the advance notice that actually allows planning an intervention.
An alert becomes maintenance only when a response flow exists
Every alert must point to a responsible person or function, a timeframe for awareness, and a verification procedure. Without these elements, the notification may go unanswered during shift changes or compete with other occurrences without common criteria.
A daily routine between maintenance and production can review open alerts, compare asset condition by unit, and decide what enters the schedule. The record should preserve the signal that prompted the action, what the team found, what intervention was performed, and the outcome. This helps distinguish a useful warning from an alarm that did not lead to a decision.
The pilot begins with assets having the greatest impact on downtime
Prioritize equipment whose stoppage affects safety, quality, production, or process continuity. Failure history also matters: an asset that has stopped repeatedly may offer a concrete hypothesis to test, while equipment without history requires care to avoid confusing normal variation with anomaly.
Define a baseline before installing or activating alerts. Choose the period and comparison rules considering the actual operation of the units. When plants have different loads and routines, compare equivalent assets and record these differences, rather than treating all units as identical.
Indicators must measure result and alert quality
Count alerts, but do not use that number as proof of downtime reduction. To evaluate the pilot, track unplanned downtime hours, availability, useful alert advance notice, false positives, and corrective costs. Also record how many interventions occurred because of an alert and what was found.
Avoided hours and savings require a baseline and validation of interventions. The comparison must consider asset operation and what would have happened without the action. Without this record, the team may attribute to the system a downtime that would not occur or call a merely delayed expense an economy.
Checklist to evaluate the pilot and its expansion
- The pilot covers assets chosen by criticality, failure history, and impact of downtime.
- Measured parameters correspond to failure modes the team intends to monitor.
- A baseline is defined for downtime, availability, and corrective costs.
- Each alert has a responsible party, response timeline, and intervention procedure.
- The team records inspection, action taken, and outcome for each alert addressed.
- The plan tests power and connectivity interruptions without confusing stored data with delivered alerts.
- Expansion to other units considers process differences and equivalent assets.
Expand the pilot when alerts lead to documented decisions and indicators allow comparison of results with the baseline, unit by unit.
Frequently asked questions
What distinguishes preventive and predictive maintenance?
Preventive maintenance follows intervals defined by calendar or usage, while predictive maintenance schedules intervention based on signals observed in the asset. Preventive remains useful for tasks with periodicity defined by the manufacturer or safety requirements. Predictive adds evidence about the current condition of the equipment.
Is vibration analysis sufficient to anticipate failures?
No. Vibration analysis identifies mechanical patterns, such as imbalance or wear, when adequate instrumentation and signal interpretation are available. It is a specific technique. A multivariate approach combines different parameters from the same asset, which can reveal condition changes even when a single measurement does not yet indicate a problem.
How do you choose the first assets for a pilot?
Start with assets whose stoppage most affects safety, production, or quality. Also consider failure history, time needed to obtain parts, and the ability to measure relevant signals. A small pilot with defined responsibilities and reference data usually teaches more than installing sensors on many assets without a response routine.
How do you measure if a pilot reduced downtime?
Compare unplanned downtime hours, availability, useful alert advance notice, false positives, and corrective costs against a baseline. Record each intervention linked to an alert and its outcome. Only attribute avoided hours or savings when there is evidence that the action changed the expected result.
Does data remain available if the connection drops?
The CTD Concentrator maintains battery for up to 12 hours and local data storage for up to 20 days, according to specifications provided by DROME. This preserves collection during interruptions within these limits. Local storage alone does not guarantee that alerts reach the team while connectivity is unavailable.
Read next
Predict Failures in Sewage Lift Stations
Learn how current, pressure, and pump cycles help investigate failures before shutdown, and what to evaluate when applying sensors to sewage…

Industrial Gas Leaks: Predictive Detection & Risk Mitigation
Learn how sensors and predictive analytics detect industrial gas leaks, preventing accidents and ensuring operational safety.

Analyze Seasonal Trends & Forecast Cold Chain Demand
Discover how to identify seasonal patterns and adjust forecasts to reduce losses in cold chain management with precise data.