Predictive asset monitoring only helps when a signal becomes an executable task within available time. For clinical engineering, maintenance, and quality teams, the difference between dashboard, alarm, and prediction lies in when the team can intervene. The decision depends on reliable measurements, equipment context, on-call responsible party, and documentation of actions taken.
What must happen between reading and intervention
- Associate each critical asset with failure modes that could affect operations.
- Combine related variables instead of interpreting each reading in isolation.
- Define who receives the alert, how much time they have to respond, and who assumes responsibility if there is no confirmation.
- Document assessment, decision, and intervention to verify whether the alert was useful.
Visualization, alarming, and prediction are different levels
A dashboard displays current and historical measurements. A threshold alarm triggers when a variable crosses a configured value. Prediction looks for changes that, together, indicate a failure may be approaching before the threshold is reached.
| Feature | What it informs | Operational limitation |
|---|---|---|
| Visualization | Measured value and trend | Someone must notice the change and decide what to do |
| Threshold alarm | A variable has moved outside the configured range | May alert when the process is already degraded |
| Prediction | A pattern of signals consistent with a future failure | Depends on data quality and time available to act |
A sensor recording temperature at regular intervals may reveal a gradual rise. A fixed threshold only alerts when the reading reaches the set value. Predictive analysis attempts to recognize the combination and sequence of signals preceding failure, but does not turn every variation into a diagnosis.
Data quality determines whether an alert is actionable
An alert is actionable only when the team understands which asset is involved, which signals have changed, and how much time remains to assess the situation. Missing readings, poorly positioned sensors, misaligned clocks, or expired calibration can hide a deviation or suggest a pattern that does not exist.
Consider this illustrative example, not a real case. In a cold room, the STE Satellite Sensor monitors temperature, the SDT records current and door opening, and a pressure transmitter sends its 4 to 20 mA signal to the SAD. The analysis can consider a gradual temperature rise together with a change in current and pressure, while the open door helps distinguish heat entry from normal use from another anomaly.
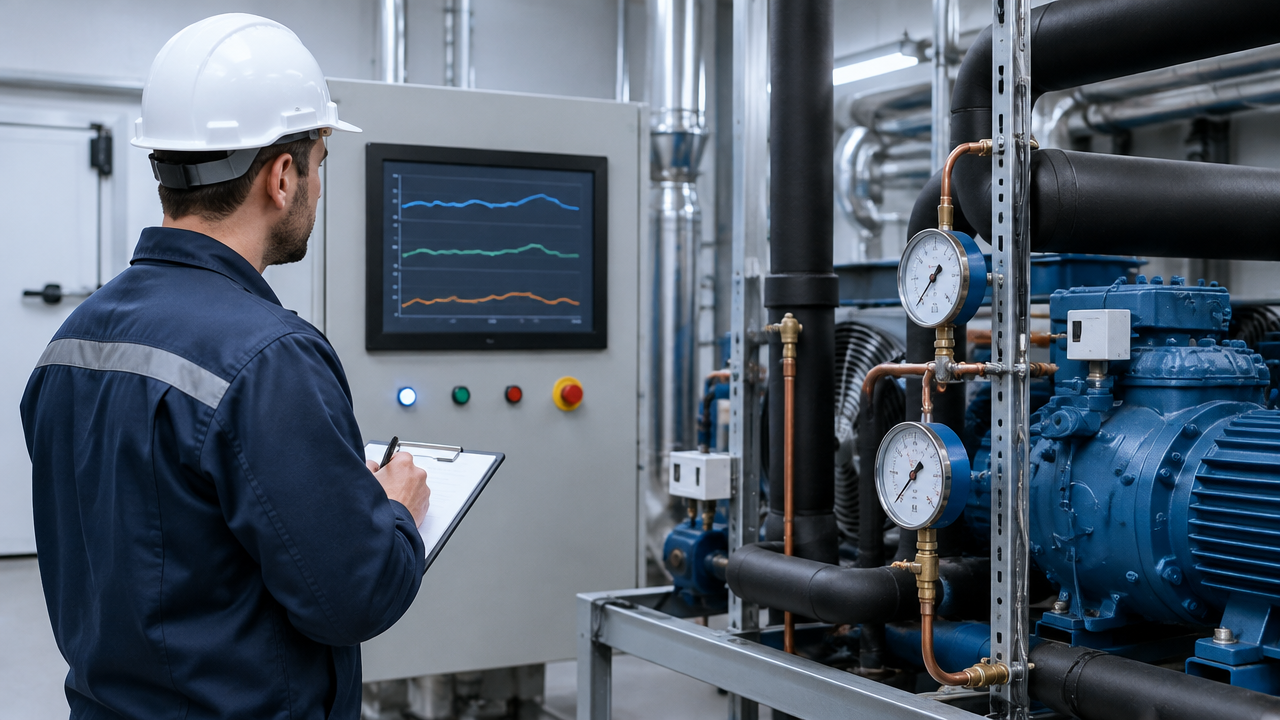
Context changes interpretation. An open door during restocking does not, by itself, indicate refrigeration system failure; a change in current must also be compared with the equipment's history and operating regime. Without this relationship, the dashboard can display correct numbers and still produce a poor decision.
The alert must arrive with context and defined destination
DROME connects STE, SDT, and SAD sensors to the CTD Concentrator. DROME Predict crosses more than 15 parameters from the same asset and, based on data provided by DROME, issues alerts 30 to 60 minutes before failure, with probable cause and suggested corrective action. This advance notice describes the system's stated operation, not a guarantee for every asset or failure mode.
The public description of DROME and the alert flow presents how readings reach the responsible team. In operation, the alert must identify the equipment, the observed condition, the urgency, and the next step. The predictive recommendation supports technical assessment; it does not automatically decide to shut down equipment or the plant.
In a chiller serving critical areas, the team may receive an indication to verify a specific condition and compare behavior with available redundancy. The responsible party evaluates risk and local procedure before maintaining, transferring load, or interrupting the asset. A useful prediction opens a window to decide; it does not replace the decision.
An operational roadmap transforms warning into maintenance
- Classify criticality. Document the clinical, operational, and material impact of failure, plus the existence of redundancy.
- Link signals to failure modes. Define which variables must be analyzed together and which data are available for each asset.
- Name shift-based responsible parties. Determine who receives, who evaluates technically, and who can authorize an intervention.
- Configure channel and escalation. Choose the channels used by the team and the timeframe to escalate the alert to the next responsible party if no one confirms receipt.
- Document the response. Record time, assessment, decision, work order, and observed result, including when no intervention is performed.
This flow prevents a notification from sitting only on someone's phone during a shift change. It also creates a history to verify whether the suggested action was applicable and whether the local procedure needs adjustment.
Measure whether alerts arrive in time to change the decision
A dashboard with many readings does not, by itself, demonstrate that maintenance has become more predictable. Track the useful advance notice of the alert, the time until someone confirms receipt, the time until technical assessment, false positives, and the number of unplanned shutdowns.
Interpret the measures together. Long advance notice helps little if the alert reaches a channel with no responsible party; a high response rate may reflect repeated notifications without action. Compare equivalent periods and document changes in sensors, configuration, routine, or equipment load before attributing a variation to the model.
Evaluate the platform by the path to the work order
Beyond the dashboard, verify how the platform associates readings with the asset, handles communication failures, shows the alert justification, and directs the notification. Check whether the team can confirm receipt, escalate the occurrence, and maintain a record that can be compared with inspection and intervention.
Ask to walk through an example with an asset similar to yours: from raw signal to documented decision. The practical criterion is knowing whether your team will have contextualized data, evaluation time, and a clear procedure before an unplanned shutdown.
Frequently asked questions
What distinguishes visualizing measurements, threshold alarms, and failure prediction?
Visualizing measurements shows current state and history. A threshold alarm warns when a variable exceeds a configured range. Prediction looks for combinations of changes that appear before failure, to provide time for diagnosis and action. Each step requires reliable data and a defined response process.
How do I monitor critical assets before a shutdown?
Start by identifying which assets could cause clinical risk, loss of supplies, or operational interruption. Define the variables that help assess each failure mode, confirm sensors and data quality, and associate each alert with a responsible party, response timeframe, and local procedure. Then review records to adjust thresholds and escalation.
Which indicators show whether predictive monitoring works?
Track the useful advance notice of the alert, the time between warning and awareness, the time until technical assessment, false positives, and unplanned shutdowns. Interpret these indicators together: many quickly answered alerts do not prove value if they arrive late or do not change the maintenance decision.
Should a predictive alert automatically stop the equipment?
Not automatically. A predictive alert guides the team's assessment; stopping equipment or the plant depends on risk, available redundancy, and local procedures. The responsible team must assess the condition, protect people and processes, and document the decision, including when deciding to keep the asset in operation.
What data are needed to predict failures in a cold room?
It depends on the failure mode you want to recognize. In a cold room, temperature, compressor current, pressure measured by a transmitter, and door opening can provide context to the same asset. Aligned timestamps, consistent readings, and maintenance records also matter, since gaps or configuration changes confuse the analysis.
Read next

Vibration in Refrigeration: How to Predict Failures
See how vibration indicators help anticipate failures in refrigeration systems and make maintenance more predictive and safe.

Prevent Sensor Corrosion in Saline Environments
Learn how to extend sensor lifespan in humid and saline areas through material selection, proper sealing, cleaning, and predictive monitorin…
Energy Backup Audit: Practical Checklist
Learn to audit generators, UPS systems and batteries with a practical checklist to reduce risks and increase continuity in critical environm…